Fighting AI Slop in Production Codebases: How Huntress Improved Fable 5.1’s API Recall
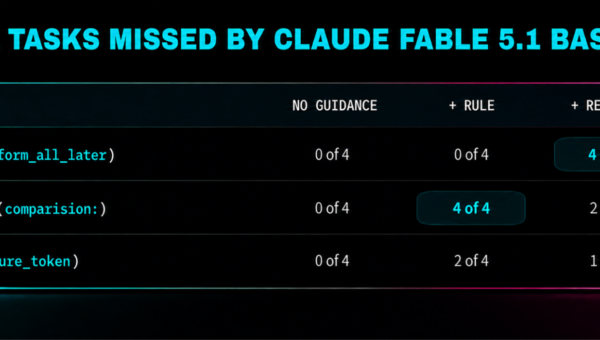
TL;DR: When Huntress tested Anthropic’s Claude Fable 5.1 in evaluations, we started with a ~48% accuracy baseline for API recall: significantly more than previous models…